AI workflow evaluation service
Evaluation centered on completed customer tasks and consequential failures.
- For
- Businesses deploying customer-facing AI assistants
- Solves
- Teams lack task-specific evidence of assistant reliability.
- Delivers
- Evaluation suite and actionable failure report
- Built in
- about 4 weeks of creation time, MVP in 5 days
- Investment
- $8,500 for the MVP, $33,000 for the full product
- Run it
- Inside your business, or as part of your offer to clients
What it does
For businesses deploying customer-facing AI assistants, turn representative tasks, reference answers and acceptance criteria into evaluation suite and actionable failure report.
- Define task rubrics.
- Create edge cases.
- Replay evaluations.
- Inspect source use.
- Compare versions.
- Track regressions.
What goes in, what comes out
- Representative tasks
- Reference answers
- Acceptance criteria
AI drafts, people review. Evidence review and quality assurance workspace.
- Evaluation suite
- Actionable failure report
How it works
The workflow
- InStart with
Representative tasks, reference answers and acceptance criteria
- 1
Agree review criteria
- 2
Ingest a sample
- 3
Generate candidate findings
- 4
Inspect supporting evidence
- 5
Let reviewers confirm or dismiss each item
- 6
Assign corrections
- 7
Recheck the affected material
- OutFinish with
Evaluation suite and actionable failure report
AI does the heavy lifting, people stay in charge
Propose possible inconsistencies, omissions and rubric matches. Combine extraction with deterministic checks where rules are explicit. Reviewers make the final judgment. Keep false positives and missed cases visible during evaluation.
What your team sees
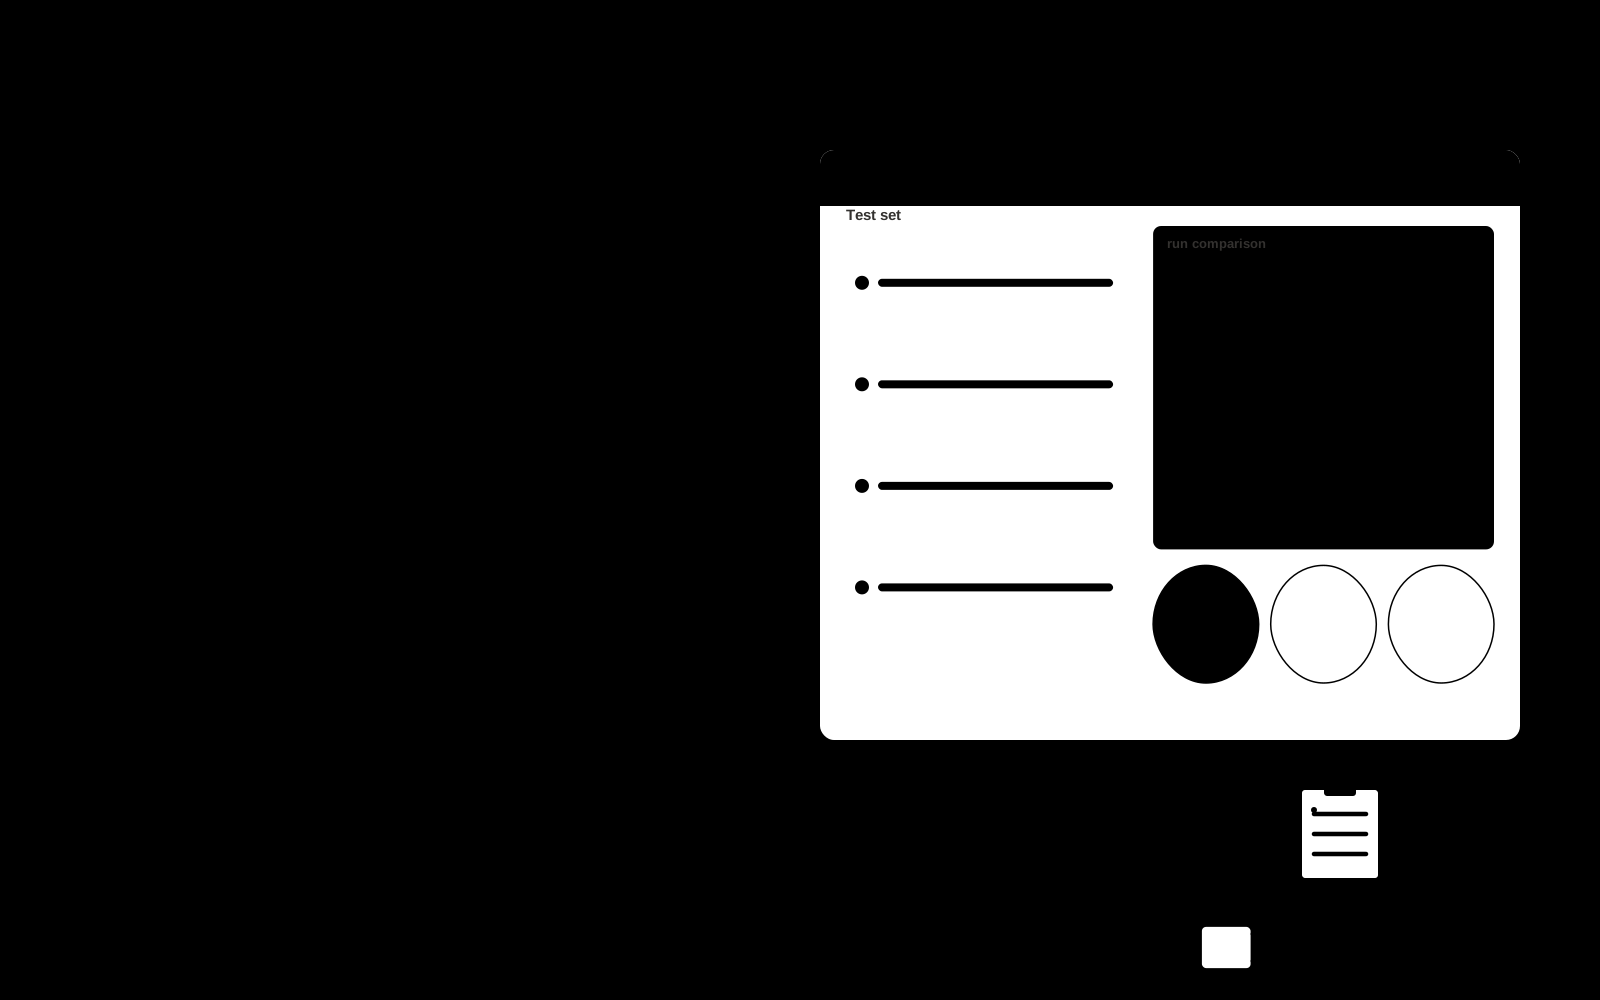
Key screens: Test set, run comparison, failure evidence. Open on a review queue ordered by reviewer-selected priorities. Show each finding beside the original evidence and applicable rule. Provide accept, dismiss and needs-information controls with reasons. A separate report view summarizes confirmed findings and unresolved items, not raw AI flags. In this product, the first view is test set, followed by run comparison and failure evidence.
Accounts and administration
Versioned review criteria, evidence links, reviewer decisions, disagreement handling, correction assignments, recheck status and exportable review history.
Integrations and data access
Authorized repositories, technical documentation, application APIs and logs. Source repositories, task trackers and report exports. Keep findings as review proposals until authorized owners accept the resulting actions. These are candidate integration categories, not verified supported connectors.
How we build it
We build with our own AI software development factory, so most implementations take days to a few weeks of creation time, not months. You see working software at every step, and exact timing depends on availability.
- 1
Scoping call
Day 1Thirty minutes on your process, your data and how you want to run it: for your own team, or for your clients. You get a fixed scope and price for the MVP.
- 2
MVP
5 daysOne buyer segment, one recurring use case; first modules: define task rubrics; create edge cases. Manual review in the loop. Built by our AI software factory.
- 3
Paid pilot
6 daysAccounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- 4
Full product
10 daysRemaining modules: inspect source use; compare versions; track regressions. Self-serve onboarding, billing, monitoring and the wider integration set.
- 5
Run and improve
MonthlyWe host, monitor and improve it for a fixed monthly fee, or hand it over to your team. How the retainer works.
Why we start with an MVP
An MVP, or minimum viable product, is the smallest version that your users can actually work with. It is not a cheap version of the full solution. It is a test, built to answer the questions that decide whether the rest is worth building.
- Pick the riskiest assumption. Here: will businesses deploying customer-facing AI assistants use it to solve "teams lack task-specific evidence of assistant reliability"?
- Build only what tests it. One team, one use case, a few core modules. People do the rest by hand for now.
- Run a paid pilot. Have a qualified reviewer independently assess the same sample.
- Measure, then decide. Track accepted task success and regression detection. Then expand, change course or stop, with evidence instead of opinions.
MVP scope for this solution. Begin with businesses deploying customer-facing AI assistants and one recurring use case. Build the first two modules: define task rubrics; create edge cases. Provide operator assistance for the third module: replay evaluations. Deliver evaluation suite and actionable failure report through a manual review queue. Perform other necessary full-scope functions manually during the pilot. Include all applicable access, accuracy and professional-review controls from the start.
After the MVP. After paid pilots establish value, automate the remaining modules: inspect source use; compare versions; track regressions. Add one validated source integration, reusable customer configuration and recurring delivery. Expand to additional teams, document formats or languages only after testing the new scope.
What the build depends on. Evidence coordinates, versioned rules, reviewer decisions and a representative reference set. Measure misses as well as confirmed findings before scaling.
Investment
A planning range to start the conversation, not a quote. You pay per phase, so you can stop after the MVP.
- Phase 1
MVP
One buyer segment, one recurring use case; first modules: define task rubrics; create edge cases. Manual review in the loop.
- Phase 2
Paid pilot
Accounts, roles, review states, audit trail and the first integration, hardened for two to three paying pilot customers.
- Phase 3
Full product
Remaining modules: inspect source use; compare versions; track regressions. Self-serve onboarding, billing, monitoring and the wider integration set.
Indicative total, MVP to full product$33,000about 4 weeks of creation time · start with the MVP from $8,500
Running costs per month
A rough indication of monthly hosting and AI model costs once it is live, not tested. Real costs depend on usage, file sizes and the models chosen.
| Stage | Hosting and infrastructure | AI usage | Total per month |
|---|---|---|---|
| MVP and paid pilotabout 3 customers | $30–$60 | $80–$160 | $110–$220 |
| Full productabout 50 customers | $110–$210 | $880–$1,750 | $990–$1,960 |
Run it or resell it
For your own team
Businesses deploying customer-facing AI assistants run it inside the business: representative tasks, reference answers and acceptance criteria in, evaluation suite and actionable failure report out, reviewed by your people.
As part of your offer
Agencies, consultancies and software companies can offer it to their own clients under their brand. We build and maintain it; you sell and deliver it.
Your brand, or this one
Run it under your own brand, or start from this concept style.
- primary
#27918d - accent
#c95466 - surface
#e4f1f0 - ink
#22201e
- Headings
- Archivo
- Text
- Lora
- Voice
- Technical, direct, no hype
Selling it to your own clients: the go-to-market playbook
Pricing to test
Test USD 1,000-3,000 for a task-specific evaluation set and reviewed baseline report. Offer recurring release evaluations on a retainer tied to case count and review depth. Prices are hypotheses.
Message to test
AI workflow evaluation service for businesses deploying customer-facing AI assistants. Evaluation centered on completed customer tasks and consequential failures. Demonstrate the claim through a task-specific assistant evaluation report.
Where to find buyers
AI implementation agencies
Lead magnet
A task-specific assistant evaluation report
The first 30 days
- Week 1: interview five prospective buyers in this segment: businesses deploying customer-facing AI assistants. Ask to see a recent example of the problem and their current process.
- Week 2: prepare this demonstration using authorized or synthetic material: a task-specific assistant evaluation report.
- Week 3: present it through AI implementation agencies and seek one narrowly scoped paid pilot.
- Week 4: review accepted task success, regression detection, total delivery effort and a concrete renewal decision before increasing scope.
Paid pilot
Have a qualified reviewer independently assess the same sample. Compare confirmed findings, false alarms and omissions. Repeat on unseen material before agreeing recurring volume. For this solution, use representative tasks, reference answers and acceptance criteria and evaluate evaluation suite and actionable failure report. Agree success thresholds with the buyer before starting; collect a baseline for accepted task success, regression detection. A positive signal is payment and repeat use with acceptable quality and delivery cost, not a favorable demo reaction alone.
Success metrics
Accepted task success, regression detection
Retention and expansion
Offer recurring reviews and rechecks of previously confirmed issues. Expand document or case types after validating the new rubric with qualified reviewers.
Why clients would pick it
A domain-specific review rubric and rights-cleared examples of confirmed defects, false alarms and reviewer reasoning. For this solution, build around evaluation centered on completed customer tasks and consequential failures. This advantage requires execution and accumulated customer trust; the base model alone is not a defensible asset.
Alternatives and positioning
Manual reviewers, checklists, generic scanning tools and specialist audit services. Differentiate on this specific proposed advantage: evaluation centered on completed customer tasks and consequential failures. Test it against the buyer's current method on the same task. Competitor coverage and uniqueness have not been established.
Main delivery costs
Document or media processing, model evaluation, expert review, false-positive handling, rechecks and customer-specific rubric calibration.
Safeguards
Protect secrets, customer data and source code. Use controlled environments, technical review and a recoverable deployment process. Validate source access and reviewer availability during the pilot. Maintain customer-level access, data deletion controls and a record of final approvals.